High Availability
Overview
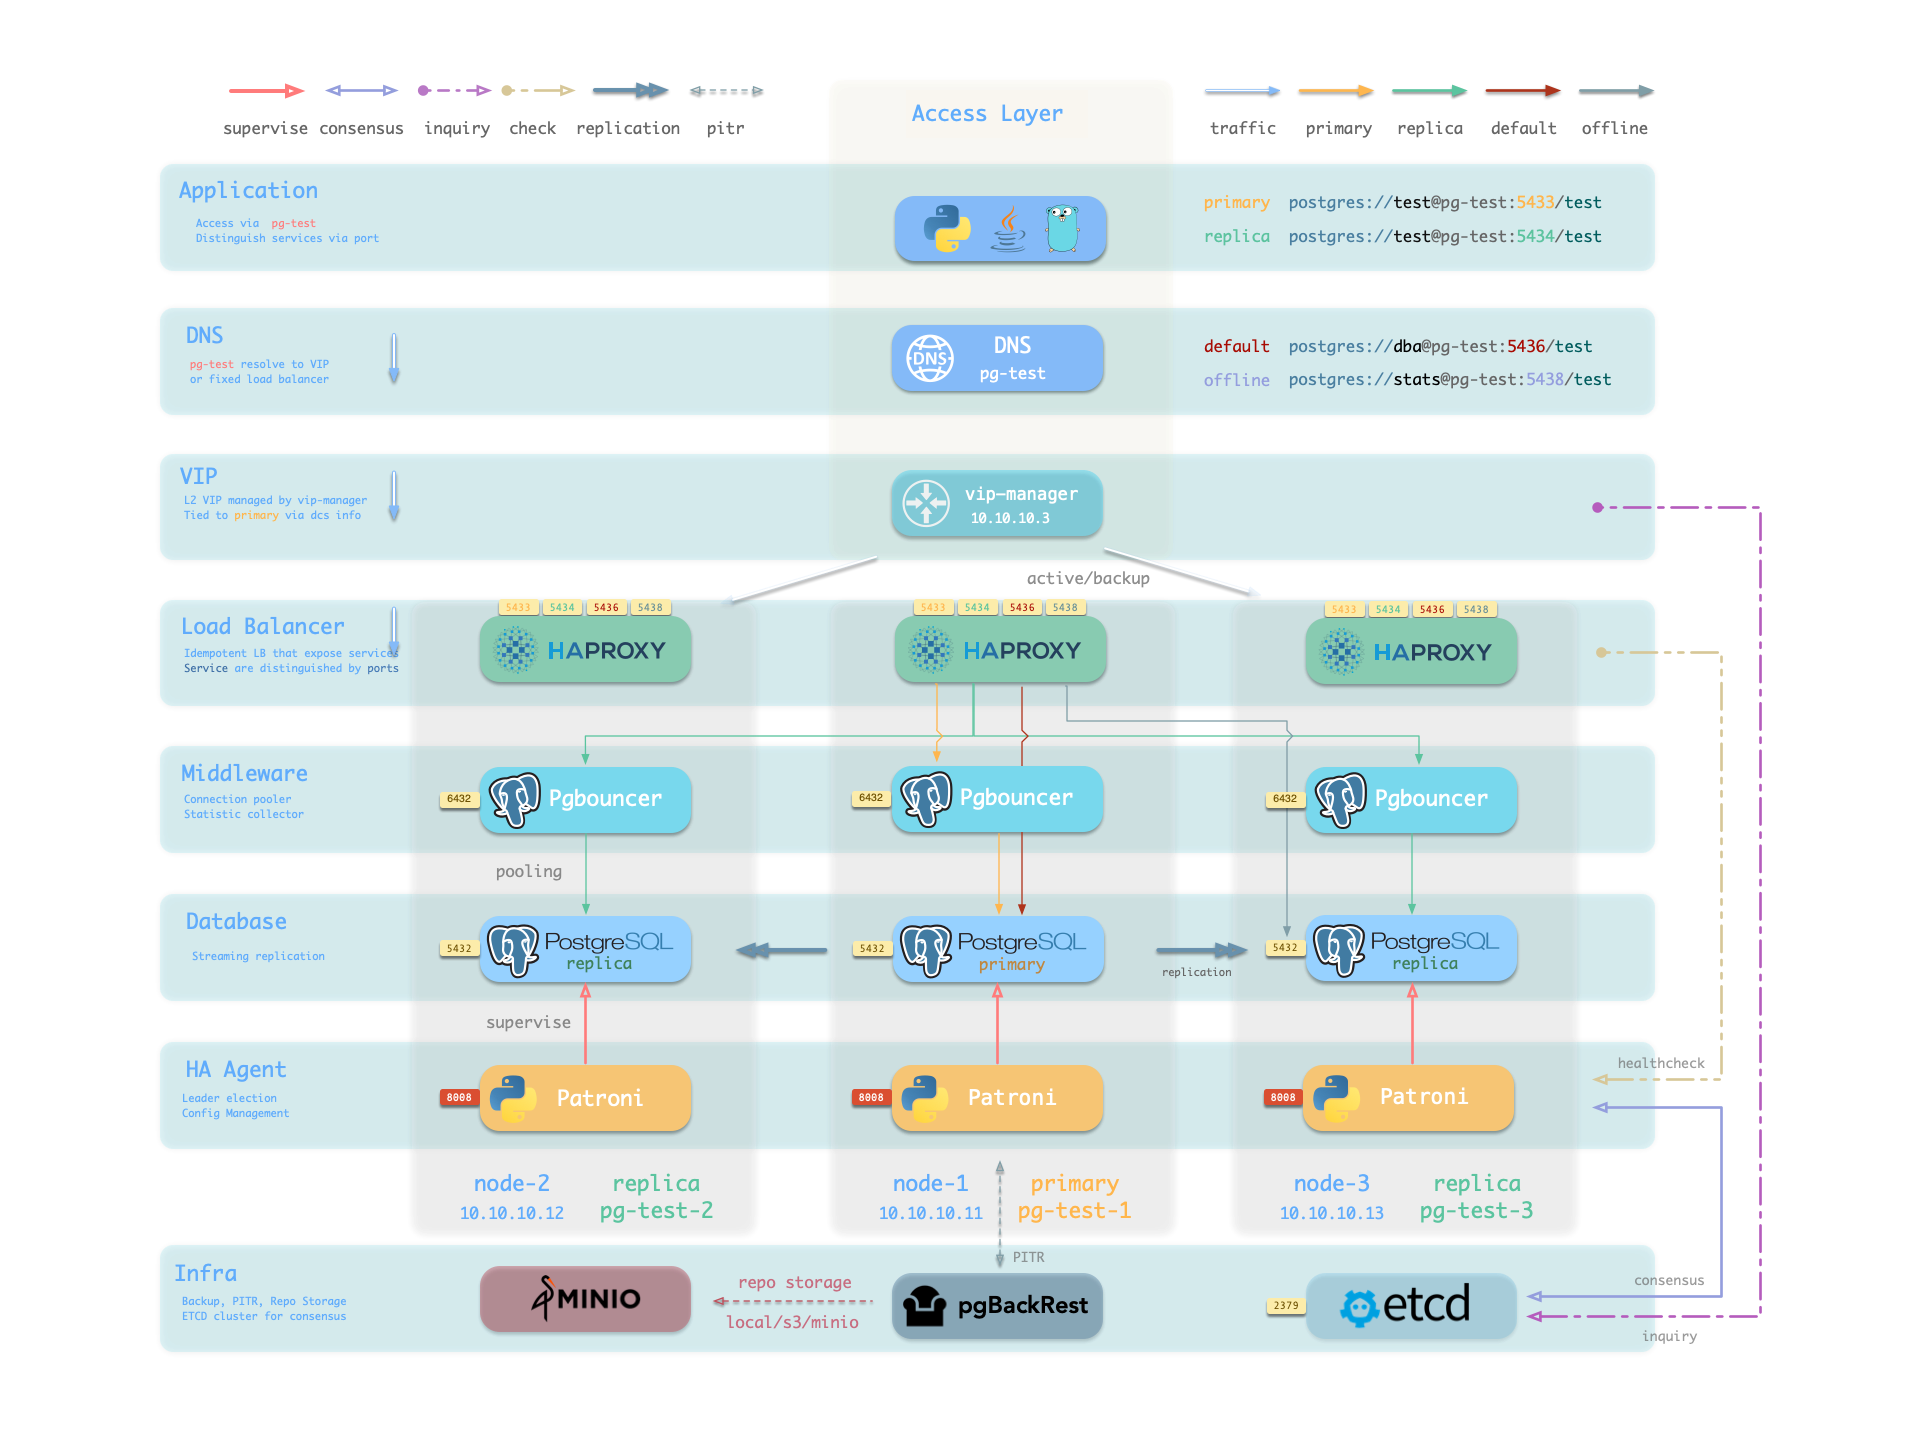
Pigsty PostgreSQL clusters include HA through Patroni, Etcd, and HAProxy.
A cluster with two or more instances gains automatic HA without extra configuration. A surviving instance can provide the complete database service. Clients can connect through any cluster node without tracking primary-replica changes.
Default norm mode targets RTO below 45 seconds. With asynchronous replication, pg_rpo=1MiB limits sampled lag for failover candidates. It does not bound actual data loss. Strict synchronous mode with crit.yml gives acknowledged transactions RPO = 0 during failover. Configure these settings for your hardware and reliability requirements.
Built-in HAProxy load balancers switch traffic automatically. Clients can use DNS, VIP, LVS, and other access methods. Failover and switchover cause brief interruptions but require no connection-string changes or application restarts. These short maintenance windows support sequential cluster maintenance and upgrades without application coordination. Automatic recovery lets staff defer hardware repairs until the next day.
Large organizations and core institutions have run Pigsty in production for extended periods. The largest deployment has 25K CPU cores and more than 220 PostgreSQL instances. Each large instance uses 64 cores, 512GB memory, and 3TB NVMe SSD storage. Over five years, this deployment maintained more than 99.999% availability despite dozens of hardware failures and other incidents.
What problems does High Availability solve?
- Improve availability in the data security C/IA model: RPO ≈ 0 and RTO < 45s.
- Perform sequential maintenance with short maintenance windows.
- Recover automatically from hardware failures without immediate staff intervention.
- Use replicas for read-only requests to reduce primary load and use available resources.
What are the costs of High Availability?
- Infrastructure: HA needs DCS, such as etcd, zk, or consul, for consensus.
- Minimum deployment: Meaningful HA requires at least three nodes.
- Resources: Each replica consumes more resources, although this is usually manageable.
- Complexity: Backup costs and operational complexity increase substantially, requiring management tools.
Limitations of High Availability
Streaming replicas receive changes in real time, including accidental or defective changes such as DROP TABLE and DELETE. HA therefore cannot recover data lost through human error or software defects. Use delayed clusters or PITR with earlier base backups and archived WAL.
| Configuration Strategy | RTO | RPO |
|---|---|---|
| Standalone + Nothing | Data permanently lost, unrecoverable | All data lost |
| Standalone + Base Backup | Depends on backup size and bandwidth (hours) | Lose data since last backup (hours to days) |
| Standalone + Base Backup + WAL Archive | Depends on backup size and bandwidth (hours) | Lose unarchived data (tens of MB) |
| Primary-Replica + Manual Failover | ~10 minutes | Lose data in replication lag (~100KB) |
| Primary-Replica + Auto Failover | Within 1 minute | Lose data in replication lag (~100KB) |
| Primary-Replica + Auto Failover + Sync Commit | Within 1 minute | No data loss |
How It Works
The HA components work together as follows:
- PostgreSQL uses standard streaming replication to build physical replicas; replicas take over when the primary fails.
- Patroni manages PostgreSQL server processes and handles high availability matters.
- Etcd provides distributed configuration storage (DCS) capability and is used for leader election after failures.
- Patroni relies on Etcd to reach cluster leader consensus and provides health check interfaces externally.
- HAProxy exposes cluster services externally and uses Patroni health check interfaces to automatically distribute traffic to healthy nodes.
- vip-manager provides an optional Layer 2 VIP, retrieves leader information from Etcd, and binds the VIP to the node where the cluster primary resides.
Primary failure triggers an election. The healthiest replica, with the highest LSN and least potential data loss, becomes primary. Read/write traffic then moves to it. From failure until promotion, writes block or fail. This write service interruption typically lasts 15–30 seconds and usually remains below 1 minute.
After a replica fails, read-only traffic moves to other replicas. If all replicas fail, the primary handles it. Queries running on the failed replica abort because their connections reset. Other available replicas immediately take over read-only service.
Patroni and Etcd detect failures together. The leader holds a lease and must renew it before its TTL expires. Default norm mode uses 30 seconds. Expiration triggers Failover and a new election.
Use Switchover to change primary without a failure. Writes experience a brief interruption before routing to the new primary. Use this for sequential server maintenance or upgrades.
Trade-off analysis for RPO (Recovery Point Objective), finding the optimal balance between availability and data loss.
Detailed analysis of worst-case, best-case, and average RTO calculation logic and results across three classic failure detection/recovery paths
Trade-off analysis for RTO (Recovery Time Objective), finding the optimal balance between recovery speed and false failover risk.
Pigsty uses HAProxy to provide service access, with optional pgBouncer for connection pooling, and optional L2 VIP and DNS access.
Was this page helpful?
Thanks—your feedback helps us improve this page.
What got in the way? (optional)